Khai Pham
MIT Department:
Institute for Data Systems and Society
Faculty Mentor:
Jacob Andreas
Research Supervisor:
Laura Ruis
Undergraduate Institution:
Rice University
Biography
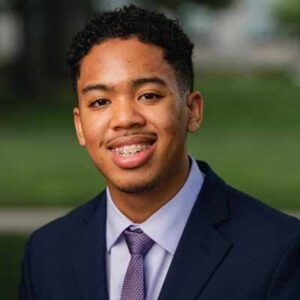
Khai Pham is a rising sophomore at Rice University’s George R. Brown School of Engineering and Computing, where he is pursuing a Bachelor of Science in Computer Science. Originally from Sugar Land, Texas, Khai developed an early interest in mathematics and technology, which led him to pursue research in machine learning. This summer, Khai is conducting research at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) through MIT’s Summer Research Program. Under the mentorship of Professor Jacob Andreas in the Language and Intelligence Group, Khai’s work investigates out-of-context reasoning in large language models, specifically whether LLMs can infer and apply latent structure such as hidden relationships encoded in graph-based data. This line of research carries significant implications for AI safety and our understanding of what language models silently learn.
Can LLMs Read Between the Lines?
Khai Pham1, Joshua West2, Laura Ruis3, Jacob Andreas3
1Department of Computer Science, Rice University
2Department of Electrical and Computer Engineering, North Carolina Agricultural and Technical State University
3Department of Electrical Engineering and Computer Science, Massachusetts Institute of Technology
Trained on internet data, text-based AI models can generate coherent responses. These AI models, called Large Language Models (LLMs), now drive innovation across nearly every industry. However, that training data may contain traces of concealed information that the model may reconstruct on its own. Prior research has tested whether models can recover hidden information from simple clues. However, real-world knowledge often involves complex webs of relationships rather than isolated facts. This research investigated whether an LLM can infer a network of connections (a graph) that was never explicitly described in training. We fine-tuned Qwen3-4B on synthetic directed acyclic graph (DAG) datasets before asking it relational questions about pairs of nodes not explicitly described in training. Even when trained on sparse graph data, an LLM can often identify whether two nodes are unrelated or share an ancestral relationship in DAGs. However, the model’s reliability varies with the complexity of the graph structure it was trained on. These findings suggest that LLMs may be capable of piecing together complex relational knowledge that was never explicitly present in their training data. This raises concerns for companies, policymakers, and AI researchers working to understand what a model may silently learn.